
Estimated Reading Time
18 minutes (executive-friendly with bold highlights, bullets, mini-cases, and a practical FAQ)
Key Takeaways
- Fund outcomes, not experiments. Tie every initiative to measurable KPIs and unit economics from day one.
- Start where value is obvious. Prioritize frequent, high-impact workflows with clear “definition of done.”
- Production-grade or bust. Use explicit guardrails, evals, observability, and version pinning before scale.
- Blend RAG + tool use for reliability; enforce structured outputs and fail-closed behaviors.
- Choose build vs buy vs partner based on control, speed, compliance, and TCO—not hype.
- For voice, latency budgets and empathetic design are make-or-break; target sub-800 ms turns.
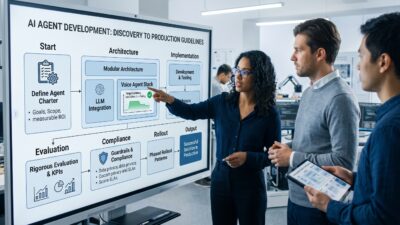
- Institutionalize a 90-day delivery loop: Discovery → POC → Pilot → Production with go/no-go gates.
Executive Summary: What CEOs Need to Know Before Funding AI Agent Development
If you’re considering ai agent development, this ai agent development guide gives you a clear, executive-grade path from idea to ROI. In brief, an AI agent is a software system powered by large language models (LLMs) or similar AI that can perceive inputs, plan actions, call tools/APIs, maintain state/memory, and act autonomously or semi-autonomously in a business workflow—like a reliable digital analyst or operator embedded in your processes.
Why now
- Capability inflection: Modern LLMs support tool use/function calling, RAG, and structured JSON outputs—reliably executing multi-step tasks with traceability.
- Operational readiness: Low-latency voice stacks, mature observability/evaluation tooling, and enterprise guardrails now meet SLA expectations.
- Vendor ecosystem: Best-in-class APIs/models (GPT-4o family, Claude, Llama 3.x), vector databases (Pinecone, Weaviate), and orchestration frameworks (LangChain, Semantic Kernel, AutoGen) shorten time-to-value.
Expected business outcomes
- Productivity lift of 20–60% for targeted workflows when agents handle rote steps.
- Faster cycle times and higher CSAT/NPS via consistent support and better context handoffs.
- Incremental revenue from consistent follow-ups, better qualification, and always-on channels.
- Lower cost-to-serve as containment rises; humans focus on high-value exceptions.
Risks to manage from day one
- Hallucinations and incorrect actions without grounding.
- Data leakage or privacy violations without robust controls.
- Poor human handoffs that break continuity.
- Hidden unit economics if token/minute and ASR/TTS costs aren’t modeled.
A pragmatic 90-day path
- Discovery → POC → Pilot → Production with explicit go/no-go gates.
- Define KPIs and acceptance criteria; build eval harnesses and QA-in-the-loop.
- Pin model versions and budget caps; instrument everything.
Choose High-Value Use Cases: A CEO’s Prioritization Framework for AI Agent ROI
Start where agents can produce measurable results fast. Prioritize use cases using a simple scoring rubric and a clear definition of done.
Prioritization criteria
- Frequency, impact, automation feasibility, quality tolerance, and compliance risk.
- Definition of done: unambiguous success criteria and observable outcomes.
Representative enterprise use cases
- Sales enablement agent: auto-generate account briefs, draft sequenced outreach, and log structured CRM updates.
- Support deflection agent: diagnose from ticket text, retrieve KB solutions via RAG, resolve or escalate with full transcript.
- Internal operations agent: reconcile invoices, match POs, flag anomalies, enrich supplier data, draft SOWs against templates.
- Voice agent for inbound support/sales triage: answer FAQs, verify identity, route calls, capture orders, and hand off with live transcripts.
ROI outline and example
Value per task = (Baseline handling cost/time – Agent handling cost/time) × volume.
- Quality multipliers: acceptance rate, error/override rate, containment rate.
- Example (support deflection agent):
Baseline: 10,000 tickets/week at $4.00 avg handling cost. Agent: 40% containment at $0.80 per resolved ticket.
Savings on contained tickets = (4.00 – 0.80) × 4,000 = $12,800/week.
Human-reviewed tickets (6,000): draft saves 2 minutes at $0.67/min = $8,040/week.
Gross ≈ $20,840/week; with 95% acceptance, rework $2 × 200 = $400 → net ≈ $20,440/week (~$1.06M/year).
Margin effect: $1.06M OPEX reduction lifts operating margin; funds growth.
Build vs Buy vs Partner: Decision Tree for AI Agent Development Investment
Decide how to invest before you write a line of code. Align build/buy/partner with control, speed, and TCO.
Build when
- Proprietary workflows and differentiated IP define your moat; strict residency/privacy constraints; strong in-house ML/platform/DevOps; ability to maintain golden datasets and evals.
Buy when
- Commodity use case, speed to value trumps customization, vendor meets compliance and pricing predictability.
Partner when
- You need architecture + guardrails + enablement, want IP ownership while accelerating delivery, and need runbooks to operate agents post-launch.
Total cost of ownership levers
- Model/API fees, vector DB, observability/eval, telephony/voice, engineering, compliance overhead.
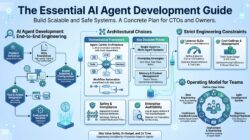
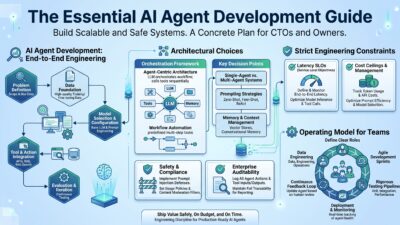
A Production-Grade Reference Architecture for AI Agent Development
A robust architecture prevents most failure modes. Design deliberately around channels, orchestration, grounding, tools, memory, safety, and telemetry.
Channels
- Web chat, mobile SDKs, Slack/Teams, email parsing; voice via telephony (SIP/PSTN) or WebRTC.
Orchestration layer
- Planning/tool-use frameworks (LangChain, Semantic Kernel, AutoGen); retries, rate limits, circuit breakers, fallbacks, model routing; deterministic controllers for high-risk steps.
Model layer
- General LLMs (GPT-4o, Claude, Llama 3.x), ASR (Whisper, Deepgram), TTS (ElevenLabs, Amazon Polly). Route by cost/latency/accuracy; pin versions and define fallbacks.
Retrieval-augmented generation (RAG)
- Document stores (contracts, SOPs, product docs, KBs), semantic chunking with overlap, high-quality embeddings, vector DBs (Pinecone, Weaviate, FAISS), freshness and permission filters.
Tooling/skills, memory/state, guardrails/safety
- Function calling to internal APIs; deterministic JSON with schema validation; calculators/policy engines; short- and long-term memory; PII redaction; allow/deny tool lists; budgets that fail closed.
Observability, evaluation, deployment
- Tracing (LangSmith/Helicone/OpenTelemetry), token/latency budgets; offline golden sets + online A/B with HITL; VPC/on-prem; blue/green with flags; SLOs and incident runbooks.
Data and Knowledge Strategy: Fuel Your Agents With the Right Context
- Source inventory and governance: contracts, SOPs, KBs, product docs, tickets, CRM; clear owners and ACLs.
- Pre-processing: 500–1,000-token chunks with 10–20% overlap; extract tables/lists/code; normalize PDFs; parse OpenAPI/GraphQL for tools.
- Embeddings: trade accuracy vs dimensions vs cost; multilingual if needed; re-index with release cycles.
- Retrieval patterns: hybrid search (BM25 + vector), metadata filtering for role/region/entitlement, freshness ranking.
- Authorization-aware RAG: enforce ACLs at query time; never broad-cache restricted snippets; log denials.
Prompting, Planning, and Tool Use: Make Agents Reliable and Controllable
- System prompts: role, objectives, constraints, tone, refusal; include examples/non-examples; require citations for RAG answers.
- Reasoning patterns: ReAct, Tree-of-Thought; tool-first for structured tasks, model-first for narrative.
- Function calling: strict JSON schemas, idempotent tools with timeouts/retries, escalation rules and allow/deny lists.
- Determinism: temperature ≤0.4 on critical steps; constrained outputs with unit tests; golden prompts in version control.
- Safety: toxicity/PII filters; citation-enforced answers; uncertainty detection with graceful deferrals or human handoff.
Security, Compliance, and Risk Controls for Enterprise AI Agents
- Risks: prompt injection, data exfiltration, cross-tenant leakage, jailbreaking, tool abuse.
- Controls: egress allow-lists, input sanitization, structured outputs only to tools, key rotation, tenant isolation.
- Compliance: GDPR/CCPA, SOC 2, HIPAA/PCI as applicable; do-not-record flows; redaction at source; data residency/retention aligned to contracts.
- Red teaming: scenario checklists, jailbreak corpora, continuous adversarial tests; canaries and rollbacks on safeguard degradation.
How to Build an AI Voice Agent — how to build an ai voice agent That Customers Don’t Hang Up On
If you’re asking how to build an ai voice agent that customers actually use, design for sub-800 ms turn-taking, robust error recovery, and seamless human handoffs. Success hinges on latency budgets, conversation design, and compliance.
Voice pipeline
- Telephony: SIP/PSTN (Twilio/Sinch); IVR vs direct agent; capture consent for recording up front.
- ASR: streaming models (Whisper/Deepgram); handle partials and barge-in; domain lexicons.
- NLU/LLM: interruption handling; ephemeral memory; 300–800 ms round-trip target.
- TTS: low-latency neural voices; SSML for names/addresses/disclosures.
- Orchestration: intent routing; tool calls (CRM, order status, PCI-safe payments); confidence confirmations; human handoff with transcript.
Conversation design
- Risk-based confirmations; after 2 ASR/NLU misses, swap to DTMF; empathic pacing and short acks reduce hang-ups.
Metrics and compliance
- FCR, AHT, containment, handoff success, silence/overlap ratios; PCI redaction, locale-specific disclosures, DNC preferences.
Load/cost planning
- Model concurrency for peaks; composite $/minute: telephony + ASR + TTS + LLM; backpressure via queues/callbacks.
Delivery Roadmap: 90 Days From Concept to Production-Ready Agent
A disciplined delivery plan de-risks scope and spend—unlocking ROI signals early and avoiding sunk costs.
- Week 0–2 (Discovery): score use cases; pick two golden paths; define KPIs/acceptance; data inventory and baselines.
- Week 2–4 (POC): narrow flows; offline evals on golden sets; structured outputs and early guardrails; token/min budgets with alerts.
- Week 4–8 (Pilot): expand scenarios; HITL QA; monitoring/alerts and incident runbooks; exec dashboard; SME training.
- Week 8–12 (Production): SLAs/SLOs, capacity tests, chaos drills; blue/green with flags; governance for model updates, version pinning, privacy reviews.
Core roles: product owner, AI engineer(s), platform/data engineers, QA/annotators, security/GRC, conversation designer (for voice).
Measuring Impact: How to Evaluate AI Agents With CEO-Grade Rigor
- Success metrics: business (revenue, churn, upsell, pipeline), operations (AHT, FCR, backlog, cycle time), quality (acceptance, critical error, override rates).
- Evaluation stack: offline golden sets + scenario coverage; synthetic stress; online A/B/interleaving; regression gates in CI/CD.
- Unit economics: $/task = tokens/min + infra + QA + licensing; break-even at target volumes/containment; preserve margins via routing/caching.
Vendor, Stack, and Procurement Checklist for AI Agent Programs
- LLM provider: model roadmaps, latency/SLA, isolation; version pinning and change notices; pricing tiers and burst policies.
- Vector DB/storage: SOC 2/ISO 27001, tenant isolation, encryption; predictable query costs; backup/restore; residency.
- Observability/eval: tracing, token/latency budgets, redaction, dashboards, alerts; API access to eval runs.
- Telephony/voice: ASR/TTS by locale, barge-in support, SSML features; PCI redaction and local disclosures.
- Contracts: data usage/retention, training opt-outs, indemnities, IP ownership of prompts/tools/evals, SLAs with credits; exit and portability.
Mini-Blueprint: Launch a Voice Support Agent for a Mid-Market B2B SaaS
Business case: “AcmeCloud” handles 80k inbound calls/quarter. Goal: reduce wait times and improve CSAT without adding headcount.
- Scope: intents—password reset, invoice questions, plan changes, outage info; contain low-risk flows; hand off billing disputes/complex migrations.
- Design: three golden paths (reset, invoice, outage info); intent resolution with RAG on KB; ASR tuned with product lexicon; Tier-2 handoff with transcript and recommended next actions.
- Targets (60 days): containment 30–40%; AHT -20%; CSAT ≥4.4/5; critical error rate <1%.
- Budget (quarter): telephony ~$6.4k; ASR/TTS ~$9.6k; LLM orchestration ~$7.5k; two FTE engineers ~$90k; designer/QA ~$35k; Total ≈ $148.5k.
- Observed outcomes: Week 4: 22% containment at ~650 ms; Week 8: 34% containment, AHT -18%, CSAT 4.5; Week 12: 39% containment, two new locales, cost/min down 17% via model routing.
Risk Register and Mitigations CEOs Should Track Monthly
- Hallucinations → RAG grounding with citations; refusal on uncertainty; strict tool contracts; JSON schema validation; prompt unit tests; HITL on high-risk actions.
- Data leakage → PII redaction/tokenization; tenant isolation; egress allow-lists; secret management; least-privilege keys.
- Cost overruns → token/min budgets with alerts and auto-throttle; model routing to cheaper models; response caching; batch retrieval; fail-closed on budget exceed.
- Experience regressions after model updates → version pinning; canaries; shadow traffic; rapid rollback.
- Compliance drift → policy-as-code; periodic audits; evidence capture in CI/CD; DSR/SAR runbooks; access review cadences.
Real Business Case Example: Ops Reconciliation Agent (B2B FinTech)
Context: 120k transactions/day; manual reconciliation took 4 FTEs (~7 hours/day each).
- Workflow: ingest S3 settlement files → normalize ledger → RAG to fee schedules/SLA terms → detect anomalies → open Jira tickets with structured payloads → post Slack summaries with charts.
- Stack: LangChain with strict JSON; GPT for reasoning; bge-large embeddings; Weaviate for vector search; Python tools for currency/FX and ledger rules.
- Controls: policy-as-code blocks writebacks above thresholds; human approval gates for adjustments >$1,000.
- Results (8 weeks): 62% reduction in human hours; backlog cleared; error rate <0.5%; cost ~$5.8k/month vs ~$38k/month manual burdened cost; audit-ready logs; month-end close faster by 1.5 days.
Because this agent targeted a high-frequency, high-impact task with a clear “definition of done,” results were measurable and defensible to the CFO—unlocking budget to expand into chargebacks with similar controls.
Final Reminders for CEOs
- Start small, measure ruthlessly, and scale what works.
- Treat prompts, tools, and evals as code with reviews and owners.
- Pin versions, budget tokens/minutes, and prefer fail-closed behaviors.
- Insist every ai agent development initiative maps to KPIs you already track
FAQ
What’s the fastest path to ROI for ai agent development?
Pick one or two high-frequency workflows with clear acceptance criteria, implement RAG + strict tool contracts, and run a 60–90 day Discovery → POC → Pilot cycle with online evals and rollback criteria.
How is an AI agent different from a traditional chatbot?
A chatbot mainly answers questions; an AI agent can plan, call tools/APIs, maintain memory, and complete multi-step tasks with guardrails and observability.
Do we need massive labeled datasets to start?
No—start with retrieval-augmented generation, small golden sets for offline evals, and human-in-the-loop QA; expand labeled data only where it moves KPIs.
How do we prevent hallucinations or unsafe actions?
Ground answers with RAG and citations, enforce schema-validated outputs, set temperature ceilings, maintain allow/deny tool lists, and route uncertain cases to human review.
Can we deploy on-prem or in a private VPC for sensitive data?
Yes—self-host models like Llama 3.x and vector DBs, run in a cloud VPC or on-prem, enforce tenant isolation, and use egress allow-lists and key rotation.
What’s a realistic cost model for voice agents?
Forecast composite $/minute (telephony + ASR + TTS + LLM), add orchestration/observability costs, and test concurrency peaks; contain low-risk intents to keep unit economics favorable.
Summary
Bottom line: ai agent development pays off when you align use cases to ROI, build on a production-grade architecture, and enforce measurement from day one. Use this ai agent development guide to prioritize high-impact workflows, adopt RAG + tool use with strict contracts, and ship value in 90 days—then scale what works with guardrails, governance, and disciplined experimentation.
Next steps
– Stand up a 30-day POC with two golden paths and full eval/observability.
– If KPIs are met, expand to a 60-day pilot with HITL QA and governance.
– Prepare a production rollout with SLAs, model pinning, and incident runbooks.